 Nia Bowers
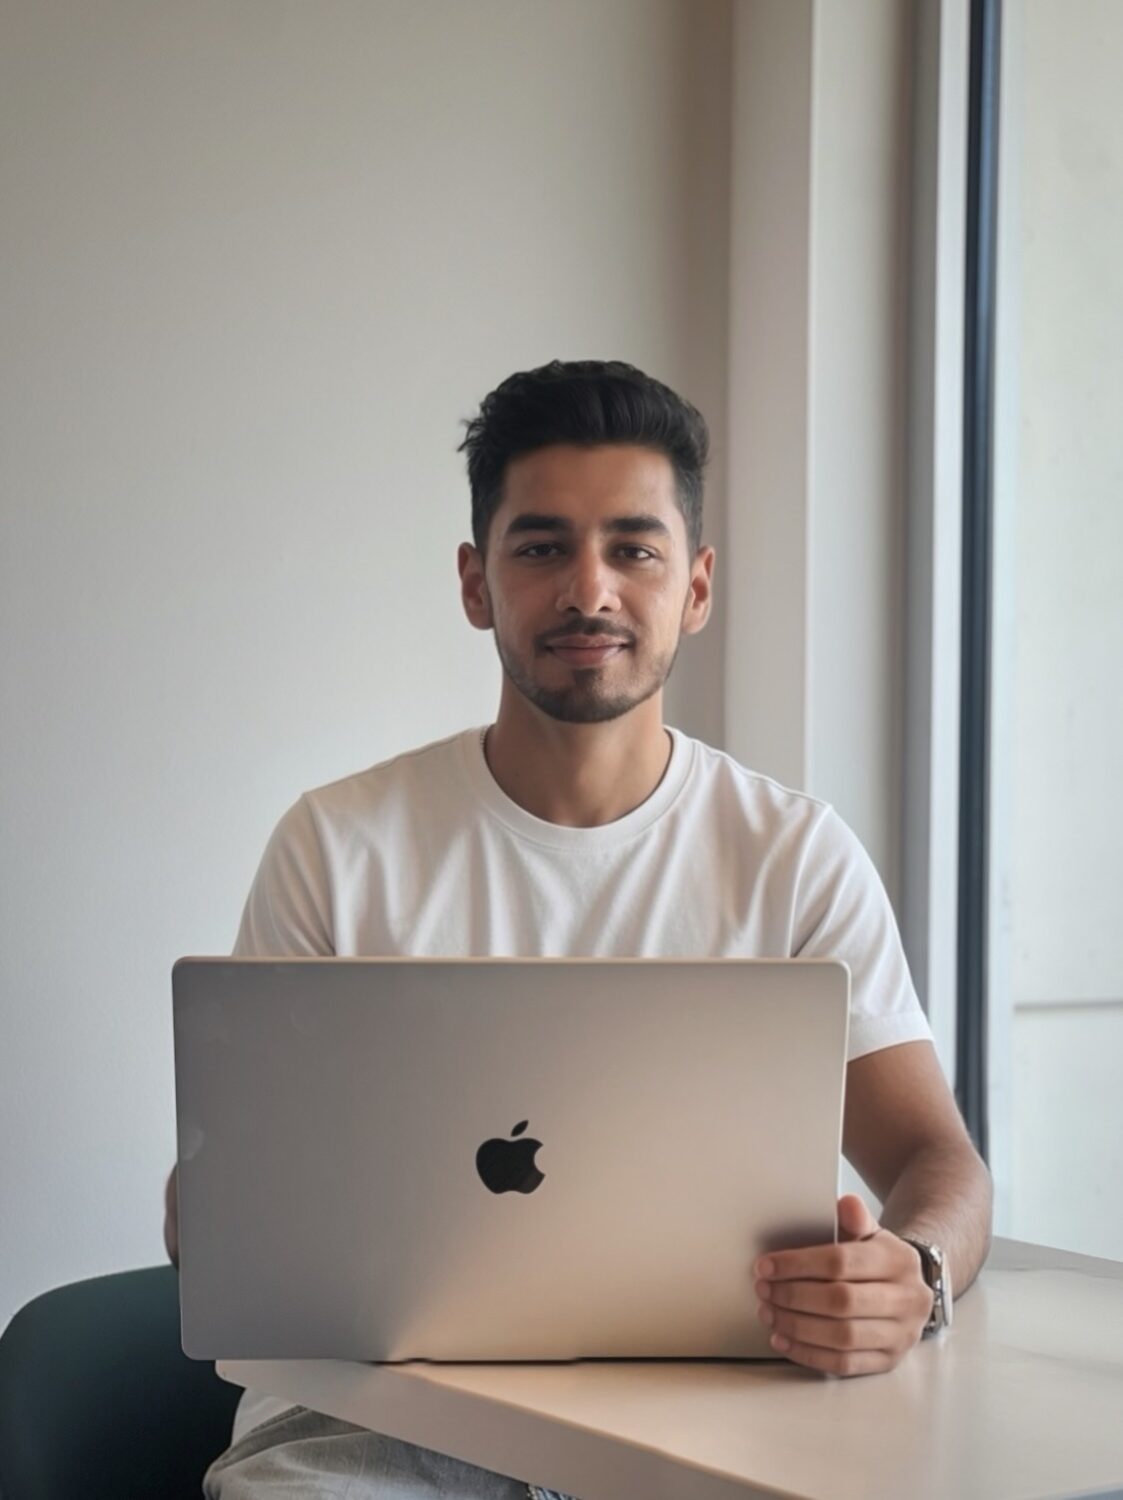
Enterprise AI discussions often begin with what models and agents can do. Arjun Gopichander Ravichander sees another question underneath them: whether the data those systems depend on is reliable enough to support the decisions they are being asked to make. As a Software Engineer III in Data Engineering he works on financial data infrastructure that can support executive reporting, AI agents, and decision science models. That overlap has given him a practical view of how decisions made deep in a data pipeline can eventually influence both business reporting and AI behavior.
Arjun argues that companies often frame this shift too narrowly as a matter of tools, job titles, or organizational structure. He sees a more basic problem in ownership. Combining teams on paper does not resolve much if no one is accountable for the quality and governance of the underlying data. That question becomes harder to ignore as organizations adopt systems that may consume information with much less human mediation than traditional reporting workflows.
“Everyone wants to ask what an agent can do,” Arjun said. “The harder question is whether you trust the data enough to let the agent act on it.”
That concern becomes more important as agentic AI moves from answering questions to completing work. Data that once passed through a person who could interpret, clean, or question it may now need to be well documented and queryable enough for an automated system to use correctly on its own.
One large migration project gave Arjun a direct example of how much depends on that underlying infrastructure. Production workflows had to move from a legacy orchestration platform to Apache Airflow within about two months, before a costly license renewal. Arjun was one of the key technical contributors responsible for helping make that transition without disrupting downstream systems. The project was completed with zero disruption and eliminated a significant recurring licensing cost.
During that project, Arjun developed an AI skill that could be used with different AI tools to analyze legacy workflow structures and accelerate repetitive parts of the migration. The skill did not remove the need for careful validation because each workflow still had to be checked systematically. It instead gave the team a way to speed up parts of the process while retaining human responsibility for the accuracy of the transition.
“AI helped us move faster, but it did not remove the need to understand what we were changing,” Arjun said. “The AI skill could accelerate repetitive work. The responsibility for validating the result and protecting the systems that depended on it was still ours.”
For Arjun, the experience reinforced a broader point about enterprise AI. Faster tools can improve execution, but they do not solve weaknesses in the systems beneath them. When financial data feeds multiple teams and automated systems, accuracy has to survive changes in infrastructure, ownership, and downstream use.
Another major project showed him a different version of the same challenge. Arjun worked on a migration project used by downstream teams across data science, AI development, business intelligence, and executive reporting. Some teams depended on undocumented behaviors in the existing system that were difficult to identify until something changed. The technical task therefore became as much about discovering hidden dependencies as moving the data itself.
Arjun helped build that visibility through lineage mapping, phased execution, and communication with teams consuming the information. The migration was completed without disrupting any of the downstream teams relying on those assets. The experience reinforced his view that a technically correct change can still create problems when enterprise systems are interconnected in ways that are not fully documented.
“A migration can be technically correct and still create a problem if another team depends on behavior nobody wrote down,” he said. “You have to assume there are dependencies you do not know about yet and build a process that gives you a chance to find them before they break.”
That same attention to the source and structure of information shapes Arjun’s view of retrieval augmented generation, or RAG. He sees clear value in retrieval systems that give large language models access to company-specific documents and current internal data. His concern is that organizations can treat RAG as a plug-and-play solution when the quality of the retrieval step still depends heavily on source data, chunking, structure, and retrieval design.
Projects like that show why enterprise data work becomes more difficult as systems expand across teams and geographies. The challenge is not only whether a pipeline works when it is launched. Engineers also have to account for changing business requirements, schema changes, and downstream uses that may evolve over time. Arjun’s work increasingly centers on making those relationships visible enough to manage before a change creates consequences elsewhere.
His next focus is broader than any one migration or pipeline. Arjun wants to work more deeply on shared infrastructure such as unified feature stores, data contracts, and lineage systems that can identify problems before they cascade across an organization. He also wants to continue building the data foundations that support agentic AI as automated systems take on more real work.
For Arjun, the next phase of enterprise AI will depend in part on whether organizations can make the information behind those systems easier to trace, govern, and maintain as their use expands. His work has increasingly focused on that layer, where architecture, ownership, and downstream dependencies determine how smoothly new capabilities can move from experimentation into production.